I don't work at Meta. But for most of the last year, a lot of us were working inside Meta's idea of what a good engineer looks like.
The idea was simple. Use AI, use a lot of it, and make sure it shows. Meta put “AI-driven impact” into its reviews and sorted engineers into tiers with names like AI Native, AI First and AI Enabled. Other companies copied the spirit, if not the labels. My team got a dashboard. It showed token count per person, per week, and everyone could see everyone else's.
You can guess what happened next.
People started feeding the dashboard. Engineers at Meta even had a name for it: tokenmaxxing. Run the agent on a task you could do faster by hand. Ask for three rewrites of a function that was already fine. Point the agent at the whole repo when it needed one file. Nobody thought any of it made them better at the job. It made the number go up, and the number was in the review.
Then, in early September, Meta stopped. A memo from two engineering leaders, reported by The Information and WIRED, said AI dashboards and token counts won't be used to judge impact anymore. The review guidance now says the work “can be supported by AI or other means.” What matters, according to the memo, is the quality, speed and complexity of the work. A Meta spokesperson said the tiers were never used in ratings anyway.
I think the change is right. I also noticed what it didn't come with.
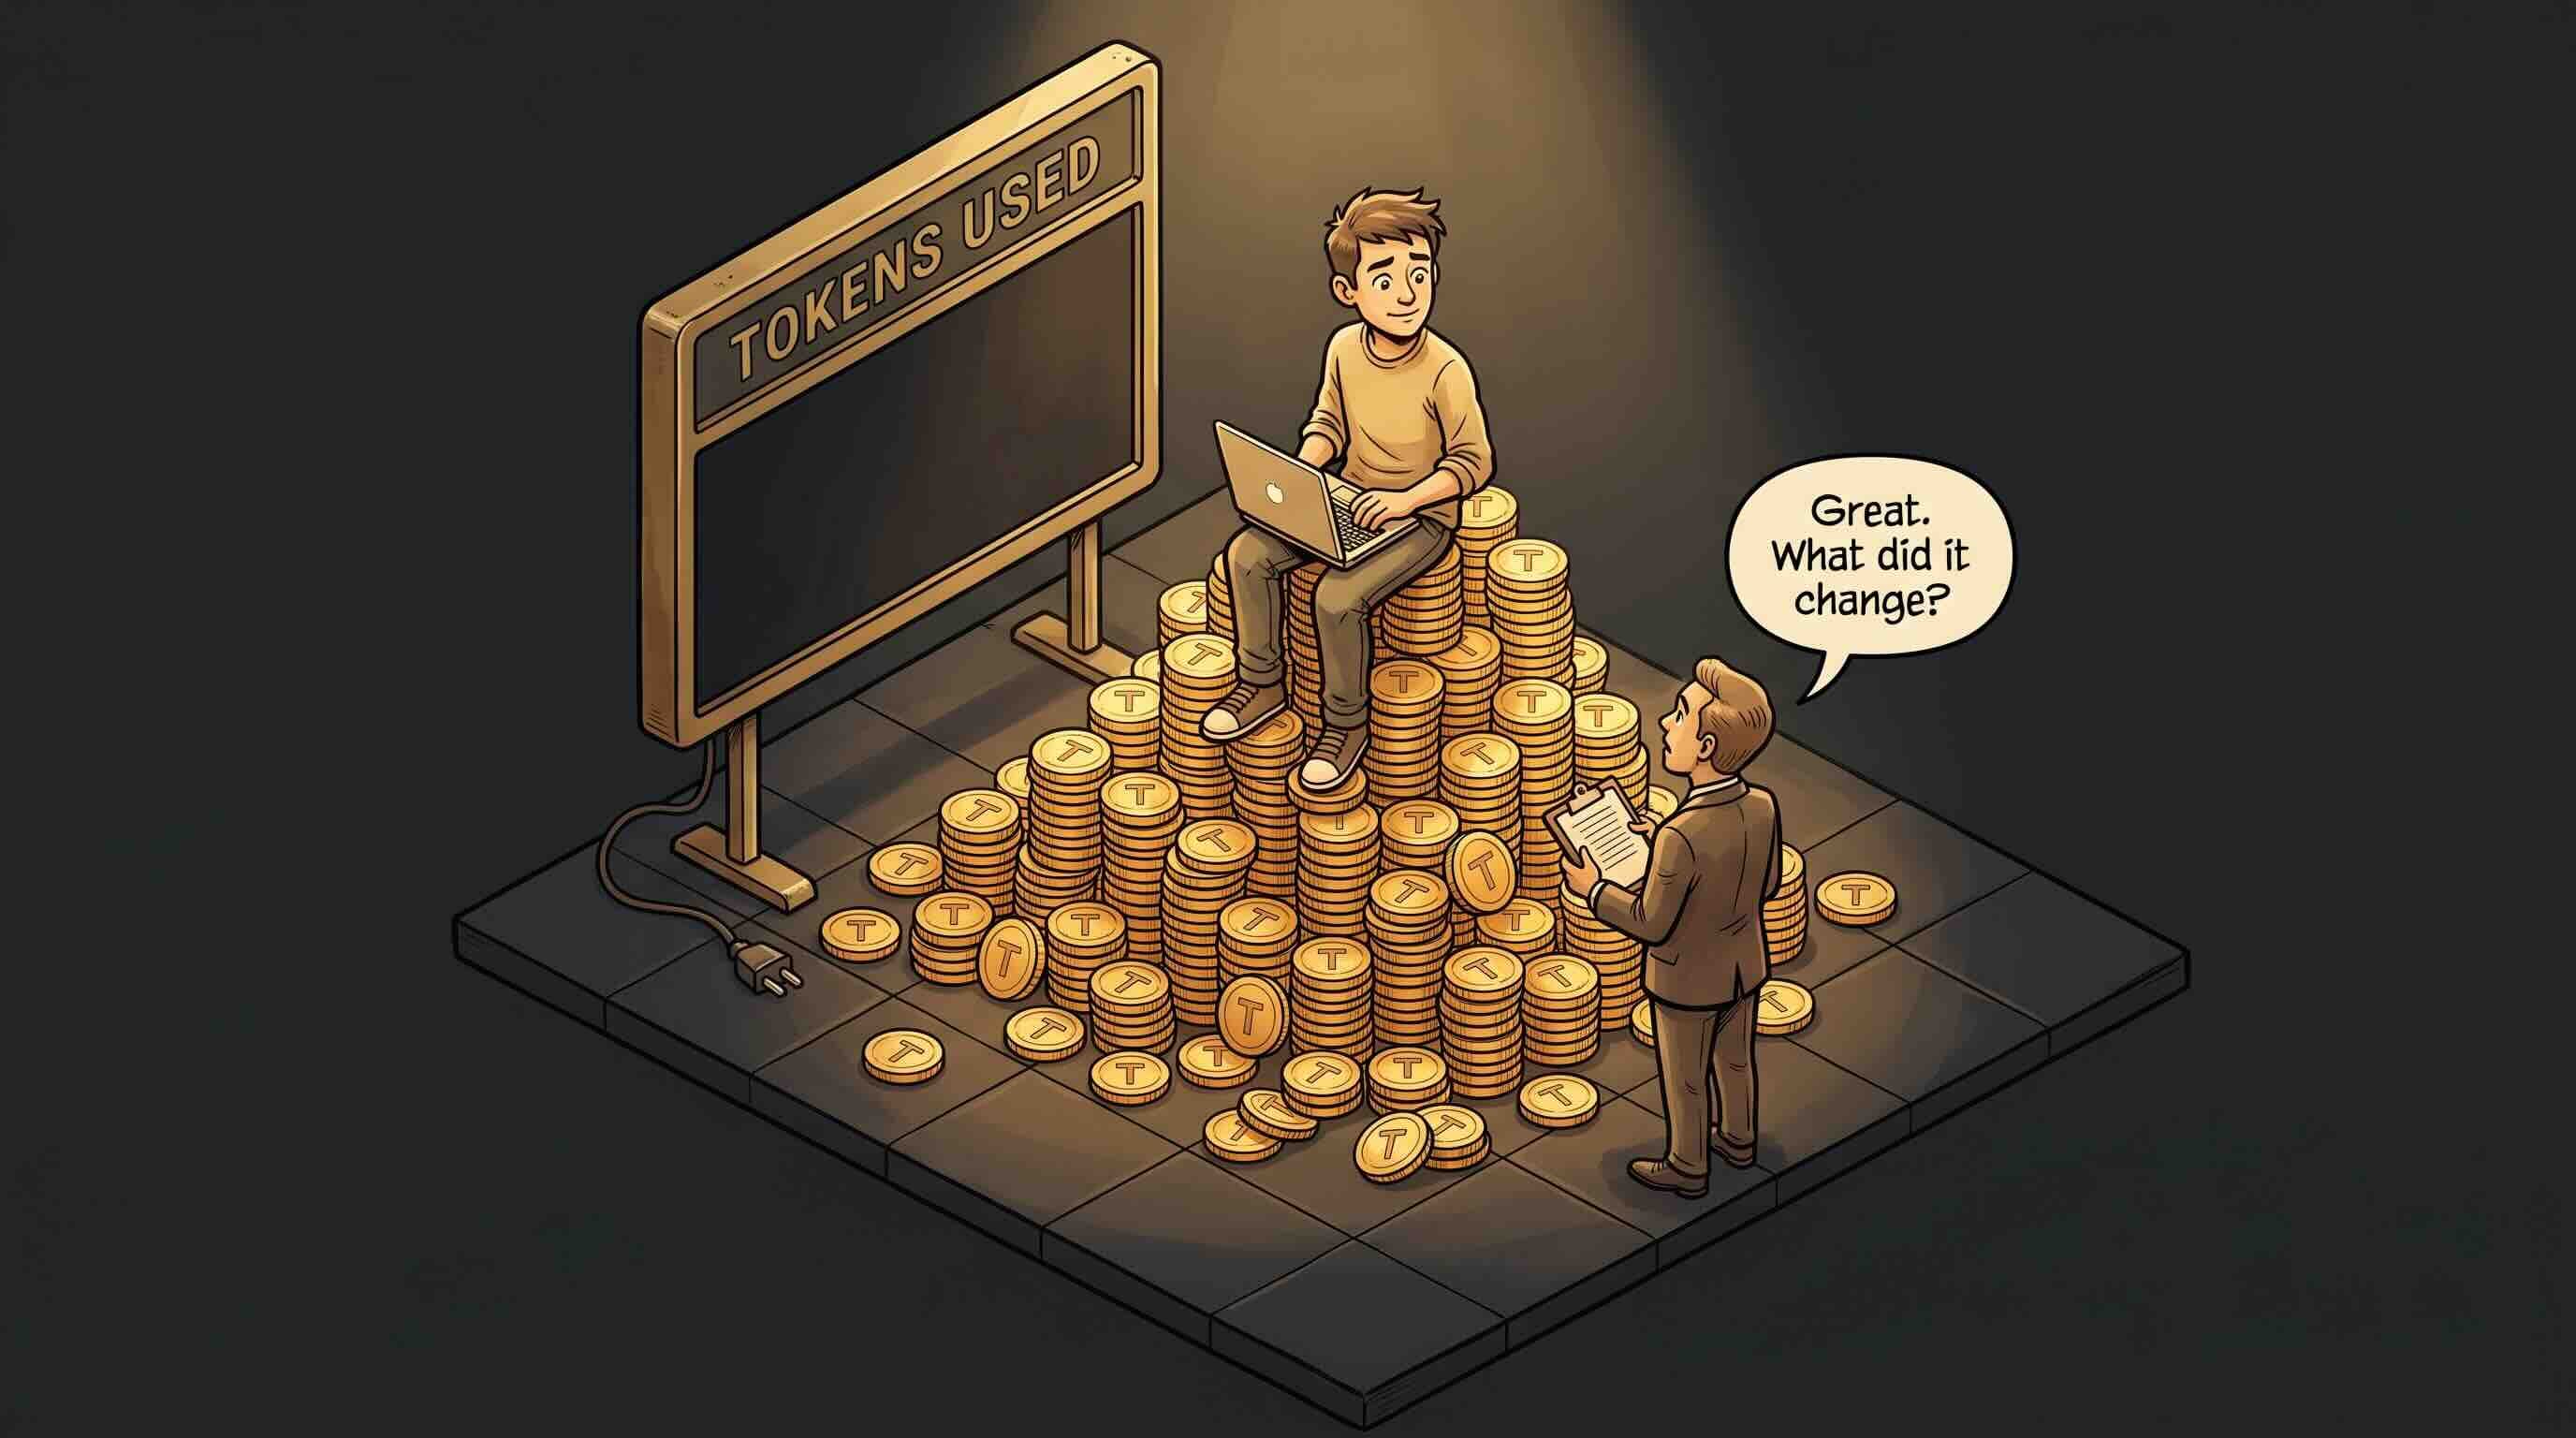
The token count was a bad measure, but it was a measure. It sat in a dashboard, timestamped, ready to paste into a self-review. The thing that replaced it, impact, has no dashboard. Nobody sends you a weekly chart of the quality and complexity of your work. You're expected to just know, and to be able to say it out loud in October.
So the bar moved from “show me your usage” to “show me what changed because of you.” It's the better bar. It's also the one most of us kept no records against for a whole year, because we were busy feeding the other one.
A friend on a platform team said it plainly when we talked last week. “I can tell you exactly how many tokens I burned last half. I can't tell you which of them turned into the latency fix.” The latency fix was the impact. It was real, it mattered, and it's exactly what his manager will ask about. The tokens are the only part he has a record of.
The pressure didn't fully go away either, which makes it worse. Some Meta engineers told reporters they don't believe the expectation went anywhere, and token use is still climbing while the company tests a new agent called Hatch. So now you need to show you're good with these tools without a usage chart, and show impact without an impact chart. Two questions, no evidence for either.
Nobody told us what counts instead because it's the same thing that always counted: what you shipped, what it changed, who it helped. For a while we just had a number to hide behind.
What I've started doing is boring. When something lands, I write one line about it while I still remember: what I did, what changed, who noticed. If an agent did the typing, I write down what I did around it. Did I scope it, catch the bug it missed, or decide its first attempt shouldn't ship? That last kind of call is the AI skill a manager can actually judge, and no token counter has ever captured it.
That's most of what Perfolio is for.
You log a line in plain words, the way you'd say it to a friend. Perfolio pulls out the contribution, the outcome, who benefited and any number you mentioned, and it leaves a field empty rather than guess. Each entry gets mapped against your rubric, so you can see which expectations have evidence behind them and which are still empty. If your coding agent did the work, it can log the session to Perfolio directly, tied to a real commit or PR, with your role attached: you directed it, reviewed it, paired with it, or it ran solo. Nothing lands in your record until you accept it.
And since impact always means impact on something, you can paste in your company's priorities (the answer from your internal chatbot works fine) and see how your effort actually split across them. That's the real question behind Meta's new guidance. It's a lot easier to answer when you've been keeping track all along.
Meta took a number out of your review. It didn't take out the question. This review season the token count won't be there to fill the silence, so you'll want something better to point at.